
AI Agent Observability: The Missing Layer Between Deployment and Trust

Deploying an AI agent isn’t the finish line. Learn what AI agent observability means, how it differs from evaluation, and what enterprise teams should monitor.
Traditional software is easy to picture: input goes in, a process runs, an output comes out. When something breaks, the trail is short, check the input, check the process, check the output, and the fault is usually in one of those three places.
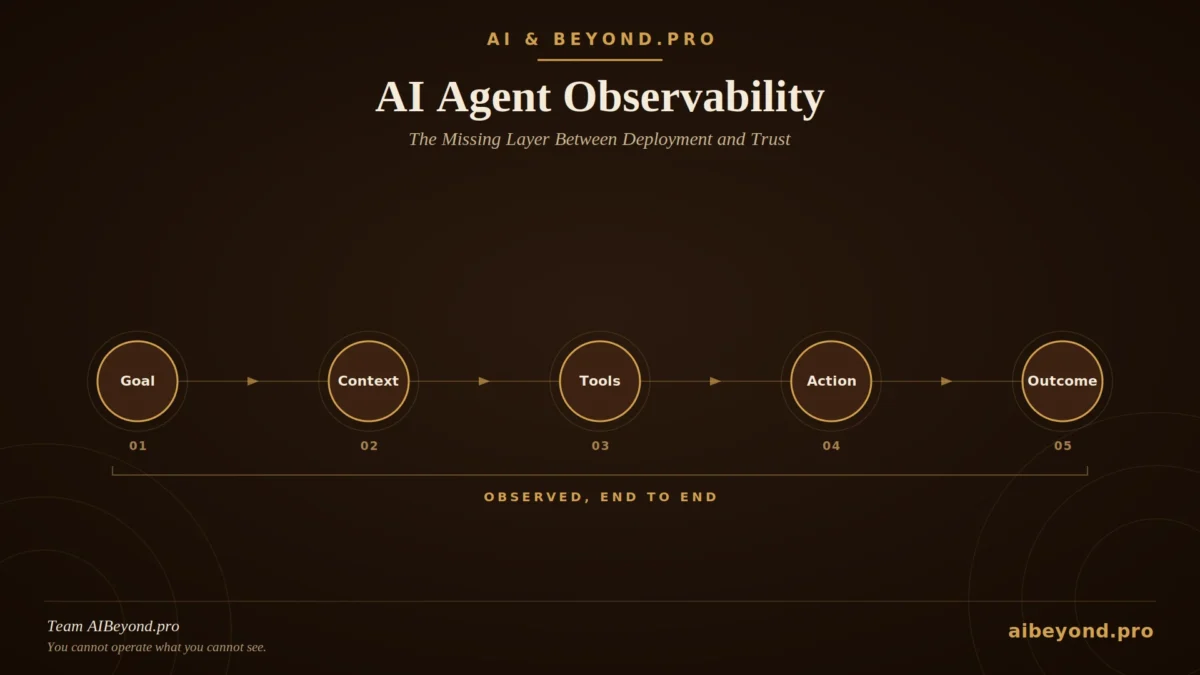
An AI agent doesn’t work that way. A request becomes a goal. The goal triggers reasoning. The reasoning pulls in context. The context informs which tools get called. The tools return results that feed back into more reasoning. Eventually, an action gets taken and an outcome appears.
Goal → Reasoning → Context → Tools → Actions → Output
The trouble is that an agent can go wrong at any point in that chain and still produce an output that looks fine on the surface. It might retrieve outdated information and reason about it flawlessly. It might call the right tool with the wrong argument. It might loop through the same failed step four times before quietly giving up and returning a plausible-sounding answer anyway. None of that shows up if the only thing anyone checks is whether the final response seems reasonable.
That’s the gap this article is about. As agents move from demos into real business workflows querying systems, taking actions, making decisions with consequences the question stops being did we get a good answer this time and becomes something harder: AI agent observability can we actually see what the agent did to get there, every time, well enough to trust it running without someone checking each result by hand.
What Is AI Agent Observability?
AI agent observability is the ability to see and understand what an agent is actually doing as it works not just the final answer, but the path it took to get there.
In practice, that means having visibility into:
- Inputs what the agent was actually asked or triggered by.
- Model calls which model was used, and for what step.
- Context what information was in front of the model when it reasoned.
- Retrieval what documents or records it pulled in, and from where.
- Tool calls which tools it invoked, with what parameters.
- Actions what it actually did in the outside world: sent, updated, created, deleted.
- Outputs what it ultimately returned or reported.
- Errors where something failed, timed out, or was rejected.
- Latency how long each step took.
- Cost what each step and each completed task actually cost.
The idea isn’t new; it’s an extension of how software teams have long monitored distributed systems. What’s new is the shape of the thing being monitored. The OpenTelemetry project the open standard most observability tools are now built on has spent the past two years extending its conventions specifically to cover generative AI: recording which model handled a step, how many tokens it used, and, increasingly, which tools it called and with what results. That extension exists because, as the project’s own engineers put it, generative AI workloads introduce telemetry that traditional monitoring was never built to capture.
Why Normal Application Monitoring Isn’t Enough
Conventional application monitoring is built around a fairly stable set of questions: Is the service up? How fast is it responding? Are requests erroring out? Is the infrastructure healthy? Those questions still matter for any system an AI agent runs on, and nothing here argues for dropping them.
But they don’t touch the thing that makes an agent an agent: the reasoning and decisions happening between the request and the response. An uptime dashboard has nothing to say about questions like:
- Did the agent use the right tool for this task?
- Did it retrieve the right information, or the most convenient information?
- Did it take the correct action, and was that action reversible?
- Did it loop unnecessarily, retrying a step that was never going to succeed?
- Did it follow the workflow it was supposed to, or improvise a shortcut?
- Did its behavior change after the underlying model was updated?
These are business questions as much as engineering ones. A support agent that’s technically “up” 99.9% of the time but regularly calls the wrong internal tool isn’t a reliability win it’s a slow-moving liability that an uptime chart will never flag.
Observability vs. Evaluation
It’s easy to conflate observability with evaluation, because both are about AI quality. They answer different questions, and a mature AI operation needs both.
Evaluation asks: did the system perform well? It’s a judgment, usually made against a rubric, a benchmark, or a set of test cases: was the answer accurate, was the task completed, was the output safe.
Observability asks: what actually happened inside the system? It’s a record, not a judgment: which steps ran, in what order, with what inputs, taking how long, costing how much.
Context visibility matters here too: a trace that shows what was retrieved, as discussed in The Context Window Trap, is often the difference between noticing that an agent reasoned over stale or irrelevant material and simply seeing a wrong answer with no explanation.
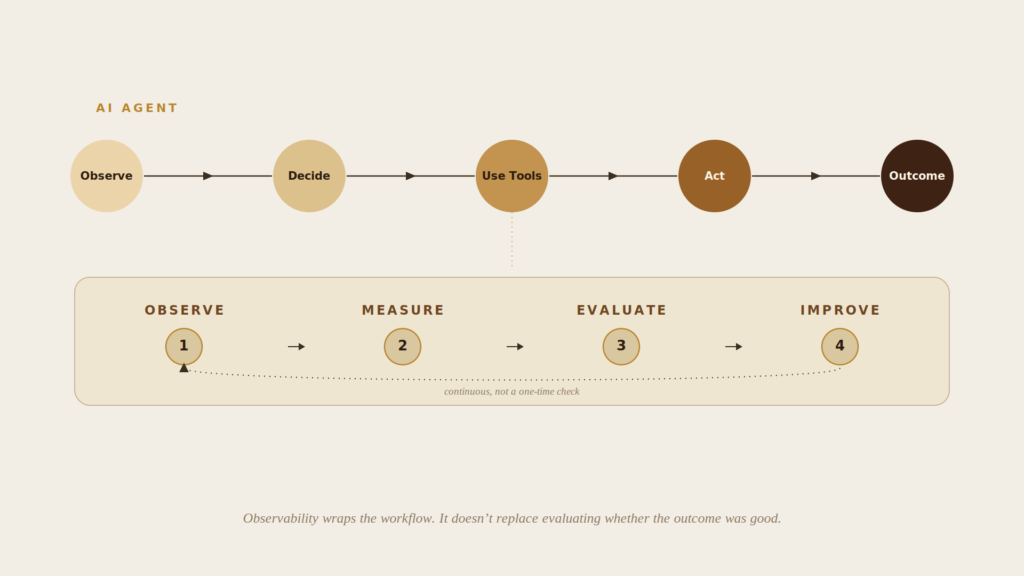
Evaluation without observability tells you something failed without telling you where or why. Observability without evaluation tells you exactly what happened without telling you whether it was good. Our earlier piece on The AI Evaluation Gap made the case that a working demo isn’t proof an AI system performs reliably; observability is the record that makes a real evaluation possible once an agent is live, because it supplies the traces evaluation needs to diagnose rather than just score. Put together, they form a loop: observe what happened, measure it, evaluate whether it was good, and use that to improve the next version the same loop, repeated continuously rather than run once before launch.
What Should Businesses Monitor?
A workable observability setup doesn’t need to track everything a system is technically capable of logging. It needs to cover a handful of areas that map to where agents actually go wrong.
01 Agent decisions
What the agent chose to do at each step, and where the system supports it a trace of why. Without this, a wrong outcome is a mystery rather than a diagnosis.
02 Tool usage
Which tools were called, with what parameters, and what came back. Tool misuse is one of the most common and most fixable agent failures, but only if it’s visible.
03 Retrieval and context
What information the agent actually had in front of it when it reasoned. An answer built on a stale or irrelevant document looks identical to a correct one unless someone can see what was retrieved.
04 Task completion
Whether the agent actually finished what it set out to do, not just whether it stopped and returned something.
05 Errors and failure paths
Where things broke, timed out, or got rejected and whether the agent recovered sensibly or pushed ahead regardless.
06 Latency
How long each step takes, since a slow step buried in a longer workflow is easy to miss until it’s affecting every task that depends on it.
07 Cost
What each run actually costs, end to end model calls, tool calls, retries tracked per completed task rather than per request, so cost can be weighed against the value delivered.
08 Human intervention
How often and where a person had to step in. A rising rate of intervention on a task that used to run cleanly is often the earliest sign something has changed.
The New AI Failure Mode
Traditional software mostly fails loudly: an exception, a crash, an error code. Autonomous agents can fail quietly, producing an output that looks complete while something underneath went wrong. A few realistic examples, not research findings, just the kinds of failures that show up once agents are doing real work:
- An agent picks a plausible but wrong tool for the task, and gets a result that’s wrong in a way nobody double-checks.
- It retrieves outdated information and reasons over it flawlessly, producing a confident answer built on a stale fact.
- It makes several unnecessary tool calls to get an answer it could have reached directly, quietly inflating cost.
- It loops through the same failed reasoning step repeatedly before giving up and returning a generic response instead.
- It completes most of a multi-step task and stops short of the last step, with no clear signal that anything is incomplete.
- It takes an action with less context than the situation actually required, because nothing forced it to check first.
- It behaves differently after a model or prompt update, in ways nobody notices until downstream complaints pile up. This isn’t hypothetical: a widely cited 2023 study tracking a major LLM service over several months found its behavior on identical tasks shifted meaningfully between versions a reminder that “the same system” can quietly stop being the same system.
None of these produce an error message. They produce an output that looks fine until someone checks the path that led to it which is precisely the layer observability is meant to expose.
A Practical AI Agent Observability Framework
Step 1 Define what “good” looks like
Before deciding what to monitor, define what a successful run of this agent actually means which tools it should use, what a completed task looks like, what counts as an acceptable outcome. Observability without a definition of good is just a pile of logs.
Step 2 Map the agent workflow
Lay out every step the agent can take: what triggers it, what it can access, which tools are available, where it can take real-world action. You can’t monitor a path you haven’t mapped.
Step 3 Track decisions, tools, and context
Instrument the workflow so each of those steps actually gets recorded not just the final input and output, but what happened between them.
Step 4 Connect observability with evaluation
Feed what observability captures into the evaluation process, so a failing evaluation score has a trace behind it that explains where things went wrong, rather than leaving the team to guess.
Step 5 Review performance continuously
Treat this as an ongoing loop, not a one-time audit. Models change, data changes, usage patterns change and quiet degradation is exactly the kind of failure that a single pre-launch check will never catch.
What Enterprise Teams Should Ask
Five questions are usually enough to tell whether an organization actually has observability, or just assumes it does:
- Can we see what the agent actually did, step by step?
- Can we identify where a failure occurred, not just that one happened?
- Can we explain why a particular action was taken?
- Can we measure cost and performance over time, not just at launch?
- Can we detect when an agent starts behaving differently than it used to?
If the honest answer to more than one of these is no, the gap probably isn’t the model. It’s the layer meant to watch it the same blind spot behind the broader pattern covered in The AI Governance Gap: Agents Deployed Faster Than Controlled.
FAQ schema
What is AI agent observability?
AI agent observability is the ability to see and understand what an AI agent is actually doing as it works its inputs, reasoning context, tool calls, actions, errors, latency, and cost not just whether its final output looks correct.
How is AI agent observability different from AI evaluation?
Evaluation asks whether the system performed well, usually against a rubric or benchmark. Observability asks what actually happened inside the system which steps ran, in what order, and why. Evaluation judges; observability records.
Why isn’t traditional application monitoring enough for AI agents?
Traditional monitoring tracks uptime, latency, and infrastructure errors, but says nothing about whether an agent used the right tool, retrieved the right information, or followed its intended workflow the questions that determine whether an agent’s output can be trusted.
What should businesses monitor in an AI agent?
At minimum: agent decisions, tool usage, retrieval and context, task completion, errors and failure paths, latency, cost, and how often a human had to intervene.
The Bottom Line
Deploying an AI agent is not the finish line. It’s closer to the starting line of a different, less visible problem: understanding, monitoring, and improving a system that is now making decisions and taking actions on its own, inside a business that depends on getting that right.
AI agent observability isn’t a nice-to-have layered on top of a working system. It’s what makes it possible to trust the system in the first place to know, not assume, that it’s doing what it’s supposed to do. The more autonomy we give AI, the more visibility we need into how it behaves.
